Few-Shot Prompting Explained: Show the AI What Good Looks Like
Few-shot prompting explained: zero-shot vs. few-shot, how to pick 2 to 5 examples, the mistakes that skew answers, and when newer models need none.
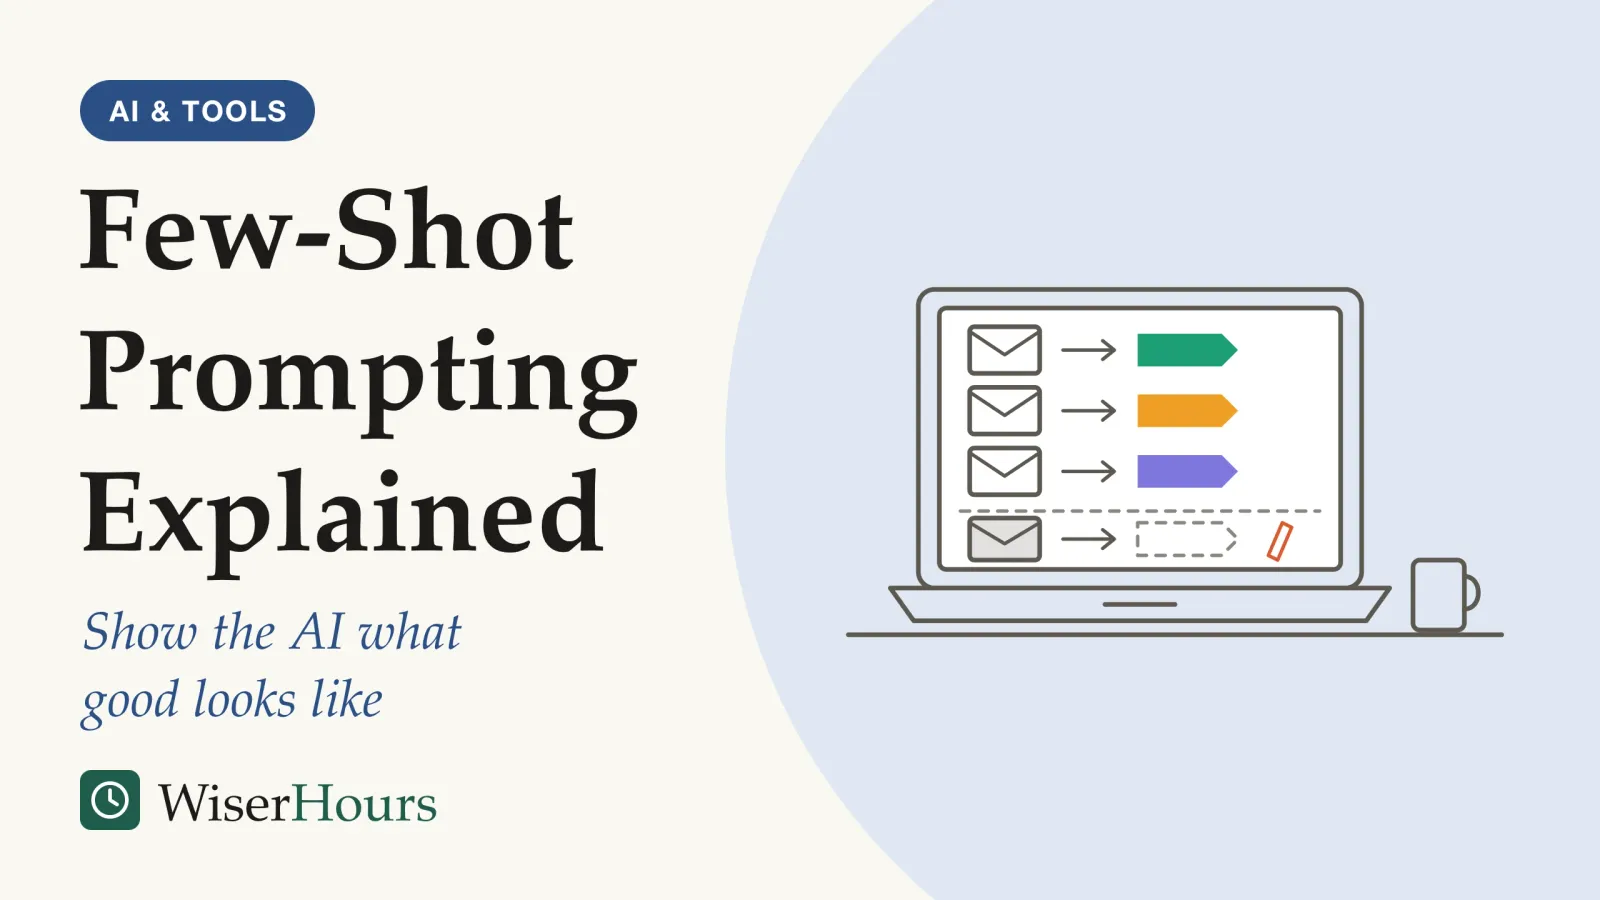
A support lead asks a chatbot to tag this week’s customer emails as refund, bug or question. The tags come back in a dozen spellings, from “Billing issue” to “Refund request (urgent)”. She pastes in three emails she has already tagged, each followed by its tag, and the next batch comes back in her three words.
Few-shot prompting is the name for what she did: putting a handful of worked examples, each an input paired with the answer you want, into the promptprompt: The instruction or input a person gives a generative AI system, such as a question, a description of a task or a block of pasted text. The same request worded differently can produce noticeably different answers.Full entry in the glossary before the real task, so the model can copy the pattern instead of guessing it. A prompt with instructions and no examples is called zero-shot. Examples are best at pinning down the format, the labels and the tone of an answer, and the newest reasoning models often manage without them. To use few-shot prompting well:
- Try the task without examples first
- Pick two to five examples that look like your real cases
- Write every example in the same format, and mark it as an example
- Mix the answers and shuffle their order
- Test on fresh cases and check for copied details
For the parts of a request that come before any examples, see the basics of writing a good prompt; if chatbots are unfamiliar, begin with a plain guide to how AI assistants work.
What is few-shot prompting?
Few-shot prompting teaches an AI model a task inside the prompt itself: you show it a few examples of the task done right, then give it a new case to complete. The approach was popularized by a 2020 paper from OpenAI researchers introducing GPT-3, which called it in-context learning because the model learns from the text in front of it and nothing inside the model changes.1
A language model writes by predicting what text should come next. Three emails, each followed by a one-word tag, then a fourth email followed by an empty tag line, set up a pattern whose likeliest continuation is another one-word tag. Google’s guide for its Gemini models describes the same thing in plainer terms: the model looks for patterns and relationships in the examples and applies them to its answer.2
“Rewrite this in our style” leaves the model to guess what the style is. Two before-and-after pairs show it: how long an item runs, how it opens, whether it uses bullet points. Reach for examples when the hard part of a task is easier to show than to describe, such as a format, a fixed set of labels or a tone.
Zero-shot vs. few-shot prompting
Zero-shot prompting gives the model only an instruction, one-shot prompting adds a single example, and few-shot prompting adds several. The 2020 GPT-3 paper defined all three and treated them as points on a scale: zero-shot is the most convenient for the person asking, while each added example gives the model more to go on. The authors also explained why zero-shot can be “unfairly hard”. Asked to make a table of world records for the 200-meter dash, a model, or a person, has to guess which columns to include and in what order, and even careful wording may not settle it.1
The study
Moderate evidence
GPT-3 given zero, one or dozens of examples (OpenAI, 2020)
OpenAI’s researchers tested GPT-3, a model with 175 billion parameters, on more than two dozen language benchmarks with no examples, one example and as many examples as fit in the prompt, usually 10 to 100. On TriviaQA, a set of trivia questions answered without looking anything up, it got 64 percent right with no examples, 68 percent with one and 71 percent with 64 examples. On many tasks, examples helped larger models more than smaller ones, which the authors read as larger models being better at learning from the prompt.1
The company was testing its own model on benchmarks, and GPT-3 was a raw text predictor that had not been trained to follow instructions.1 Chat assistants trained on instructions came later, and they change how much examples add. If a plain instruction gets you most of the way, stay with zero-shot, and add an example when the answers change shape from one try to the next.
Why examples work: they show the shape of the answer
Examples mostly teach a model what kind of answer you want, more than which answer is right. In a 2022 study from the University of Washington and Meta AI, randomly swapping the labels in the examples barely lowered results across 12 models, including GPT-3, on classification and multiple-choice tests. What did matter, the authors found, was what the examples revealed: the set of possible answers, the kind of text the model would be given, and the overall format.3 A model already recognizes a complaint about a double charge; what it cannot know is that you want the single word “refund” back, with no explanation.
That finding is no excuse for careless examples. A 2023 study by Google researchers reported that large models can override what they already know when the examples contradict it, while smaller models tend to ignore such examples, so a mislabeled example can pull a capable model the wrong way.4
How many examples should you give in a few-shot prompt?
Two to five examples suit most everyday tasks in a chat assistant. Anthropic’s guide for its Claude models recommends three to five examples for best results.5 Google’s Gemini guide advises experimenting with the number and warns that with too many, the model may start to overfit its answers to the examples.2
Benchmark tests agree. In the 2022 University of Washington study, tests on two smaller models found that even four examples clearly beat none, while adding more beyond about eight barely changed the results.3
A team sorting survey comments into four themes might give one example per theme, and a fifth for the pair of themes people most often confuse. Start with three examples, add one when a particular kind of case keeps coming back wrong, and stop adding when the answers stop improving.
Five steps to a few-shot prompt that holds up
A reliable few-shot prompt is tried without examples first, then built from a few varied, consistently formatted and balanced examples, and tested on new cases. The steps rest mostly on English-language benchmark tests of 2020 to 2023 models, so adjust them to what your own trials show.
1. Try the task without examples first
Try the task first with a clear instruction and no examples. OpenAI’s advice for its reasoning models is to start without examples and add a few if your requirements for the output are more complex.6 If the answers are right but arrive in a different shape each time, or the labels drift, examples are the fix. If the answers are wrong on substance, look first at the material and instructions you gave.
2. Pick two to five examples that look like your real cases
Examples close to the real inputs work better than random ones. In 2022 tests by researchers at Duke University and Microsoft, choosing examples similar to each new question gave GPT-3 better results than examples picked at random on several benchmarks.7 Past work is the easiest source, such as last month’s tagged emails; strip out names and anything confidential first.
3. Write every example in the same format, and mark it as an example
Showing the format of the answer is one of the main reasons to add examples, according to Google’s Gemini guide, which asks for the same structure in every example, down to line breaks, spacing and the markers that separate examples.2 Anthropic suggests wrapping examples in tags such as <example> so the model can tell them apart from your instructions.5 Keep the examples consistent with your written instructions too: OpenAI warns that differences between the two may produce poor results.6
4. Mix the answers and shuffle their order
Unbalanced examples tilt the answers toward whatever appears most often or comes last. In 2021 tests on GPT-3 by researchers at UC Berkeley and other US universities, a smaller GPT-3 model given three positive film-review examples and then one negative labelled nearly 90 percent of new reviews negative, because the last example weighed more than the majority. The same study found that reordering the same examples could move GPT-3’s accuracy on a sentiment task from near chance to near the best published results.8
- The instruction: the task and the answers allowed
- Two to five examples, each a realistic input paired with the answer you want, every label used at least once and the order mixed
- The same layout in every example, marked off as examples so the model can tell them from your instructions
- The new case in the same layout, with the answer left open for the model to fill
Give each label at least one example, avoid ending on the label you fear is overused, and if results swing, shuffle the order and compare.
5. Test on fresh cases and check for copied details
Run the finished prompt on five or ten cases that are not among the examples. Models can lift specific content from examples: in a fact-completion test in the 2021 Berkeley study, GPT-3 repeated answers that appeared in its examples more often than it should have, especially those placed last.8 Anthropic asks for examples varied enough that the model does not pick up patterns you did not intend.5 If every example mentions the Lisbon office, check that the Nairobi update does not mention Lisbon.
Check a few-shot prompt before daily use
Two few-shot prompts for everyday work
Both prompts below can be copied and adapted. OpenAI’s own prompting guide uses a close relative of the first, classifying customer reviews, and asks for a diverse range of inputs with the outputs you want.9
Sorting emails into fixed labels
Tag each customer email with exactly one label: refund, bug or question. Reply with the label only.
Email: I was charged twice for my March order.
Label: refund
Email: The export button does nothing when I click it.
Label: bug
Email: Can I add a second user to our plan?
Label: question
Email: [paste the new email, with the customer’s name removed]
Label:
Each label appears once, every example has the same two lines, and the prompt ends on an open label for the model to fill. If one kind of email is tagged wrongly again and again, such as a refund request that mentions a bug, add it as a fourth example with the label you want.
Writing in a house style
Turn rough notes into items for our weekly team update. Match the examples: a headline of under eight words, then two plain sentences.
Notes: new expense tool live, paper forms stop end of month
Item: Expenses move to the new tool. Claims now go through the new expense tool. Paper forms won’t be accepted after the end of the month.
Notes: 2nd floor kitchen closed Tues for repairs, use 4th
Item: Second-floor kitchen closed Tuesday. Repairs will keep it shut all day. The fourth-floor kitchen is open as usual.
Notes: [paste your notes]
Item:
The two examples deal with unrelated topics, so the model takes the length and tone from them and has no single subject to copy.
When to use few-shot prompting, and when newer models need fewer examples
Use few-shot prompting when the format, labels or tone of an answer matter and an instruction alone delivers them unevenly. Newer models trained to follow instructions need examples less often, and the maker of one reasoning model reports that examples made it worse, so try zero-shot first.
The shift began with instruction tuning, which trains a model on many tasks described in plain instructions. In a 2022 Google study, an instruction-tuned model with no examples beat GPT-3 given examples, by a large margin, on six of the benchmarks tested.10
Reasoning models, which work through a problem before answering, push further. OpenAI says they often don’t need examples to produce good results.6 DeepSeek, a Chinese AI company, reported that few-shot prompting consistently degraded the performance of its DeepSeek-R1 reasoning model, and recommends describing the problem and the output format without examples.11
The makers do not all agree. Google’s guide still recommends always including examples for Gemini.2 Anthropic says examples work alongside Claude’s reasoning and suggests presenting each as a problem, the method to apply and the expected answer.5
- Myth
- The more examples you give an AI, the better its answers get.
- Fact
- Gains level off after a few examples, too many can make the model copy them, and at least one reasoning model does worse when given examples.
On a reasoning model, start without examples and add them only for format or labels, and take them out again if results get worse.
How much the few-shot research can tell you
The evidence on few-shot prompting rests on benchmark tests run between 2020 and 2023, plus the makers’ guidance for their current tools. No study here measured office tasks, and the models tested are older than the chat assistants most people use now.
| What it is | What the best evidence found | Evidence |
|---|---|---|
| Examples in the prompt | More examples raised GPT-3’s scores on many benchmarks, more so for larger models | Model tests, moderate: the developer’s own tests, 20201 |
| What examples teach | Format and the set of answers mattered more than correct labels | Model tests, moderate: 12 models, peer reviewed, 20223 |
| Choosing similar examples | Examples close to the new input beat random ones | Model tests, limited: one workshop paper, GPT-3 only7 |
| Balance and order | Majority and last-seen labels skewed answers; reordering the same examples moved accuracy a long way | Model tests, moderate: ICML paper, GPT-3 and GPT-28 |
| Reasoning models | Examples lowered one reasoning model’s performance | Developer report, limited: one model11 |
The surest test is your own: run ten real cases with and without examples in your tool, and keep the version whose answers vary least.
The bottom line
Few-shot prompting is most useful when every answer must come back in a fixed shape, with the same labels, layout or house style. Try the task without examples first, then add three short, varied, correctly labelled examples in one consistent format, and run the prompt on a handful of fresh cases before you rely on it.
Frequently asked questions
Is one-shot prompting the same as few-shot prompting?
One-shot prompting is the special case with a single example. The 2020 GPT-3 paper treated it separately because one demonstration is how some tasks are explained to people. It is a fair start when you have only one model answer, but add a second, different example if the model starts copying the first one's details.
Do the examples in a few-shot prompt have to be real?
No. Invented examples work if they look like your real cases and are correct. Anthropic's guide for Claude even suggests asking the model to draft more examples from your first few; check any it writes before you use them. Real past cases often make the most realistic examples, but take out names and confidential details before pasting them into any chatbot.
Is few-shot prompting the same as fine-tuning?
No. Fine-tuning retrains a model on a large set of labelled examples and changes the model itself; few-shot prompting leaves the model untouched and shows it examples only inside the prompt. The 2020 GPT-3 paper contrasts the two: fine-tuning typically uses thousands of examples or more, while few-shot prompting uses a handful and no training.
Does few-shot prompting work the same way in ChatGPT, Claude and Gemini?
The idea works in all three, but the makers' advice differs. Google's Gemini guide recommends always including examples, Anthropic's guide for Claude suggests three to five, and OpenAI advises trying its reasoning models without examples first. Run the same task with and without examples in the tool you use, and keep whichever version gives steadier answers.
Sources
- Language Models are Few-Shot Learners. Brown, T. B., Mann, B., Ryder, N., Subbiah, M., et al. (2020). OpenAI; Advances in Neural Information Processing Systems 33 (NeurIPS 2020)
- Prompt design strategies. Google, Gemini API and AI Studio documentation (accessed 7 November 2026)
- Rethinking the Role of Demonstrations: What Makes In-Context Learning Work? Min, S., Lyu, X., Holtzman, A., Artetxe, M., Lewis, M., Hajishirzi, H. & Zettlemoyer, L. (2022). Proceedings of EMNLP 2022
- Larger language models do in-context learning differently. Wei, J., Wei, J., Tay, Y., Tran, D., Webson, A., Lu, Y., et al. (2023). Google Research, arXiv preprint 2303.03846
- Prompting best practices. Anthropic, Claude Platform Docs (accessed 7 November 2026)
- Reasoning best practices. OpenAI, API documentation (accessed 7 November 2026)
- What Makes Good In-Context Examples for GPT-3? Liu, J., Shen, D., Zhang, Y., Dolan, B., Carin, L. & Chen, W. (2022). Proceedings of Deep Learning Inside Out (DeeLIO 2022), ACL workshop
- Calibrate Before Use: Improving Few-Shot Performance of Language Models. Zhao, T. Z., Wallace, E., Feng, S., Klein, D. & Singh, S. (2021). Proceedings of the 38th International Conference on Machine Learning (ICML 2021), PMLR 139
- Prompt engineering. OpenAI, API documentation (accessed 7 November 2026)
- Finetuned Language Models Are Zero-Shot Learners. Wei, J., Bosma, M., Zhao, V. Y., Guu, K., Yu, A. W., Lester, B., Du, N., Dai, A. M. & Le, Q. V. (2022). Google Research; International Conference on Learning Representations (ICLR 2022)
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. DeepSeek-AI (2025). arXiv 2501.12948, version 2 (January 2026); published in Nature, 645, as "DeepSeek-R1 incentivizes reasoning in LLMs through reinforcement learning"
How we researched this
We read the 2020 GPT-3 paper and widely cited studies from 2021 to 2023 on how examples in prompts behave, mostly in full text on arXiv, plus the DeepSeek-R1 report, and checked the current prompting guides from OpenAI, Anthropic and Google on 7 November 2026. Main limitation: nearly all the research tested older models on English benchmark tasks such as sentiment and topic labels, not office work, and newer models may behave differently.
Keep reading
Chain-of-Thought Prompting: Does Asking AI to Think Step by Step Help?
Chain of thought prompting explained: why 'think step by step' lifted 2022 math scores, why 2025 tests found little gain, and 3 ways to use it now.
How to Write a Good Prompt: A Guide for Non-Technical People
How to write a good prompt in 5 steps: what OpenAI, Anthropic, Google and Microsoft agree on, and what tests found about wording, tips and expert personas.
ChatGPT vs. Claude vs. Gemini: How to Choose an AI Assistant
ChatGPT vs Claude vs Gemini compared on 5 things that matter: writing, files, Google and Microsoft apps, privacy settings and countries.
AI Chatbots for Emotional Support: Benefits, Risks, and When to See a Therapist
AI for emotional support: 48 trials found modest gains from chatbots built for mental health, but everyday chatbots are barely tested. When to get help.